
When people search for what is zero retention cybersecurity, they usually want to know whether a system can use sensitive information without creating another permanent copy. The answer depends on the exact data covered, the processing path, and the deletion rules. Our data retention principles provide a broader foundation for asking those questions before storage becomes an assumption.
Zero retention is therefore more than a short privacy statement. It is a technical and contractual position about what happens after processing, where temporary copies may appear, and which records remain necessary for security or operations. The term also varies between providers, so a serious review must examine the architecture rather than rely on the label alone.
What does zero retention mean in cybersecurity?
Zero retention means that covered information is processed for a defined task and then discarded instead of being written to persistent storage. In an AI workflow, this may include prompts, uploaded files, retrieved context, generated responses, or temporary task state.
The central distinction is between active processing and persistent storage. Data may exist briefly in memory while a system authenticates a request, runs an inference, or returns a result. Zero retention aims to prevent that information from becoming a durable record in a database, transcript store, log system, cache, backup, or training dataset.
In cybersecurity terms, this reduces the amount of sensitive material available after the original task. A later attacker, insider, litigant, or unauthorized administrator has fewer stored records to access. The reduction is meaningful, but it is limited to the information and systems actually covered by the policy.
The security glossary describes zero data retention as a service design and contractual posture, not as one universal technical standard. That distinction matters because different providers may define covered content, deletion timing, metadata, safety monitoring, and exceptions differently.
Which data is covered, and which data may remain?
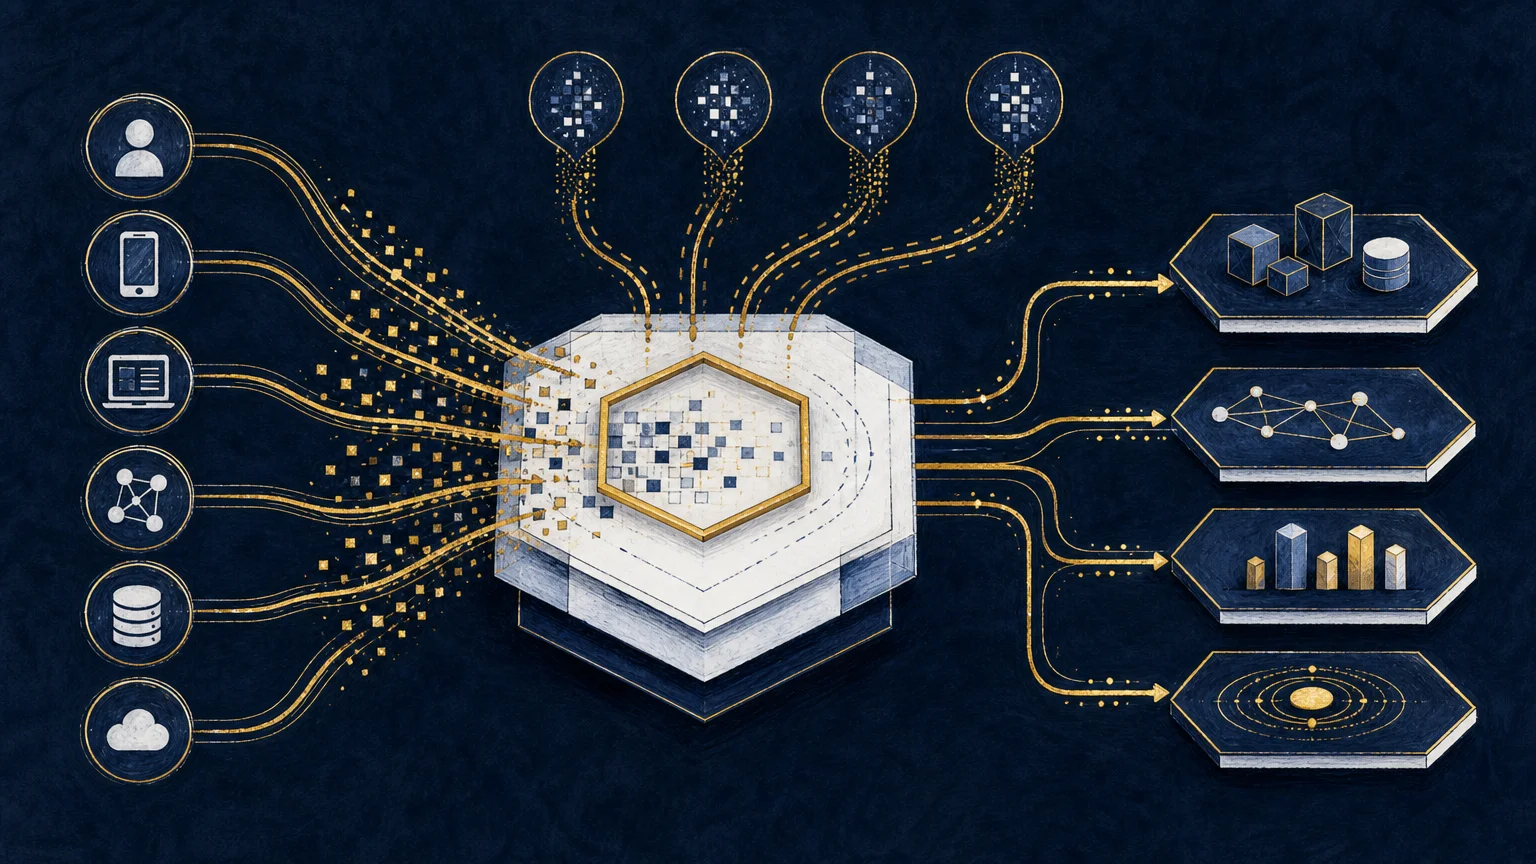
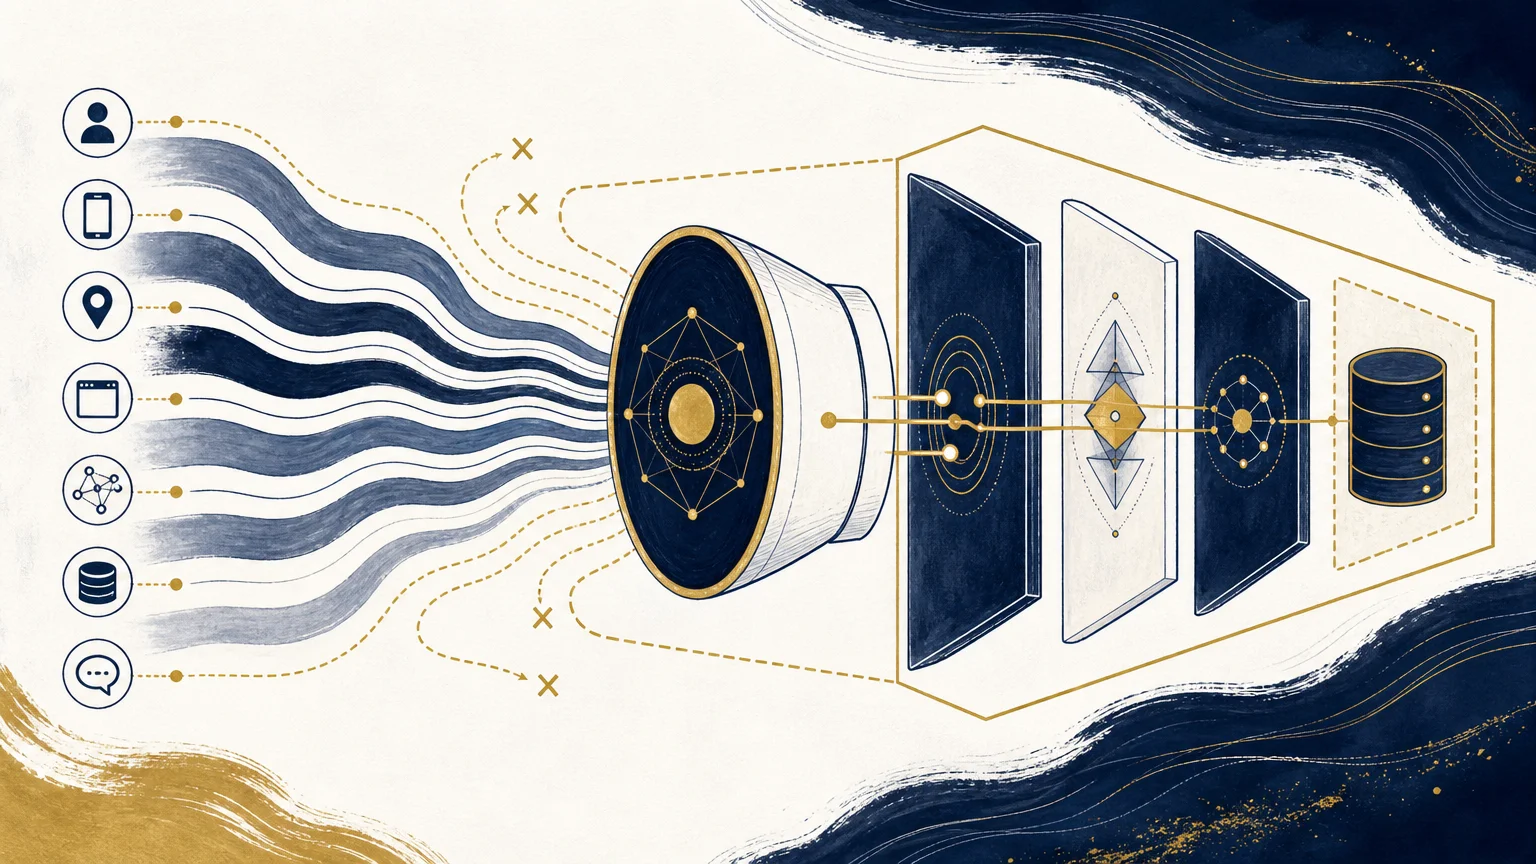
Consider an AI agent that receives a customer request, retrieves information from an internal system, calls a model, and returns an answer. A narrow zero retention policy may cover only the prompt and model response. It may not cover the customer account, retrieval system, gateway logs, or connected source database.
A complete review should classify every relevant data path:
- Request content, including prompts, files, documents, code, and user-submitted records.
- Response content, including generated text, summaries, classifications, decisions, and reports.
- Agent context, including retrieved passages, tool outputs, session state, and temporary memory.
- Metadata, including timestamps, account identifiers, IP addresses, token counts, model names, request IDs, and latency records.
- Operational copies, including caches, queues, crash reports, traces, support exports, backups, and security review records.
- Connected-system data, which may remain in a customer database, document platform, identity system, or external provider.
- Derived information, including embeddings, profiles, risk scores, summaries, classifications, and workflow outputs.
Zero retention generally concerns a defined content stream. It does not automatically erase account records, billing information, configuration, credentials, security telemetry, or records that another system must preserve. It also does not remove copies created before the control was enabled.
For AI agents, this scope question is especially important. Our page on AI agent data retention approaches memory as a lifecycle, distinguishing temporary task context, session memory, persistent memory, and derived memory. Each category has a different persistence and exposure profile.
A credible policy should therefore specify the covered fields, the retention trigger, the deletion trigger, the permitted exceptions, and the systems included. “The data is deleted” is incomplete unless the provider explains which data, from which layer, and within what timeframe.
Why does removing stored data change the threat surface?
Stored information creates future exposure. It can be copied, indexed, misconfigured, accessed by privileged personnel, included in a backup, disclosed during an investigation, or combined with another dataset.
Persistent storage also extends the period during which an incident can occur. A sensitive prompt may be relevant for only a few seconds, but a retained transcript can remain useful to an attacker months later. Removing unnecessary copies shortens that exposure window.
This does not make the processing event harmless. Information still travels across networks, reaches infrastructure outside the immediate user device, and may be visible to services that handle authentication, routing, safety checks, or abuse detection. Zero retention reduces later persistence. It does not prevent initial disclosure.
The security benefit is strongest when the system avoids unnecessary data before processing. If a request contains a full customer record when only one field is needed, deleting the request afterward does not change the fact that excessive information was transmitted.
Zero retention can also reduce secondary use. A provider that does not retain covered content has fewer opportunities to reuse it for unrelated analytics, profiling, product development, or model improvement. However, this protection depends on the policy covering the relevant content and downstream processors.
For security teams, the practical outcome is a smaller data lifecycle. There are fewer persistent targets, fewer copies to discover, and fewer locations to include in deletion or incident response procedures. The trade-off is that investigators may have less historical evidence after an event.
What does zero retention not solve?
A security team may enable zero retention and still face serious risks. The control addresses persistence, not every stage of collection, transmission, access, inference, or action.
First, zero retention does not stop sensitive data from reaching a provider. A confidential contract, production database extract, or credential may leave the organization even when the provider deletes it afterward. Upstream filtering, redaction, data classification, and access governance remain necessary.
Second, zero retention does not eliminate metadata. A system may retain the fact that a request occurred, the account that initiated it, the endpoint used, the time of access, or a security decision associated with the request. Metadata can reveal relationships, behavior, timing, and operational priorities.
Third, zero retention does not control connected systems automatically. An AI agent may retrieve information from a customer relationship platform, send data to a search provider, write results to a ticketing system, or store files in a separate workspace. Each destination has its own retention and access rules.
Fourth, zero retention can reduce observability. If full prompts and outputs disappear immediately, teams may struggle to reproduce a failure, investigate abuse, validate a decision, or respond to a complaint. A responsible design may preserve narrowly scoped security telemetry without storing full content.
Fifth, legal and operational exceptions may apply. An organization may need to preserve a regulated record, maintain a transaction history, investigate misuse, or respond to a lawful request. Zero retention cannot override an obligation that applies to a different record or entity.
Finally, the control does not replace least privilege. An agent that receives too much access can still expose or change sensitive information during the active task. Data minimization and permission minimization address different parts of the attack surface.
How is zero retention different from other security controls?
Several concepts are often grouped together because they all sound privacy-oriented. They address different risks.
Zero retention and encryption
Encryption protects information while it travels or remains stored. It can reduce unauthorized reading, but encrypted data may still be retained for a long period. Zero retention asks whether the data needs to remain stored at all.
Zero retention and anonymization
Anonymization attempts to reduce identifiability before data is stored or reused. It can be useful, but residual information may remain linkable or become identifiable when combined with other datasets. Zero retention reduces the persistence problem by avoiding storage of the covered content.
Zero retention and a no-training commitment
A no-training commitment limits one possible use of customer data. It does not necessarily prevent logging, abuse monitoring, support access, caching, or temporary retention. A provider may promise not to train on a request while still storing it for another purpose.
Zero retention and data minimization
Data minimization asks whether the system collects and processes more information than necessary. Zero retention asks how long covered information remains after processing. Minimization should occur before retention decisions, because the safest unnecessary data is data that never enters the workflow.
Zero retention and Zero Data Protocol
Our zero-data architecture perspective treats retention as one part of a broader design question. The system should first ask whether information needs to be collected, then whether it needs to persist, and finally whether it may be reused for an unrelated purpose.
These distinctions prevent false assurance. A system can be encrypted but over-retained, anonymized but over-collected, or excluded from training while still leaving sensitive logs across several services.
How should you assess a zero retention claim?
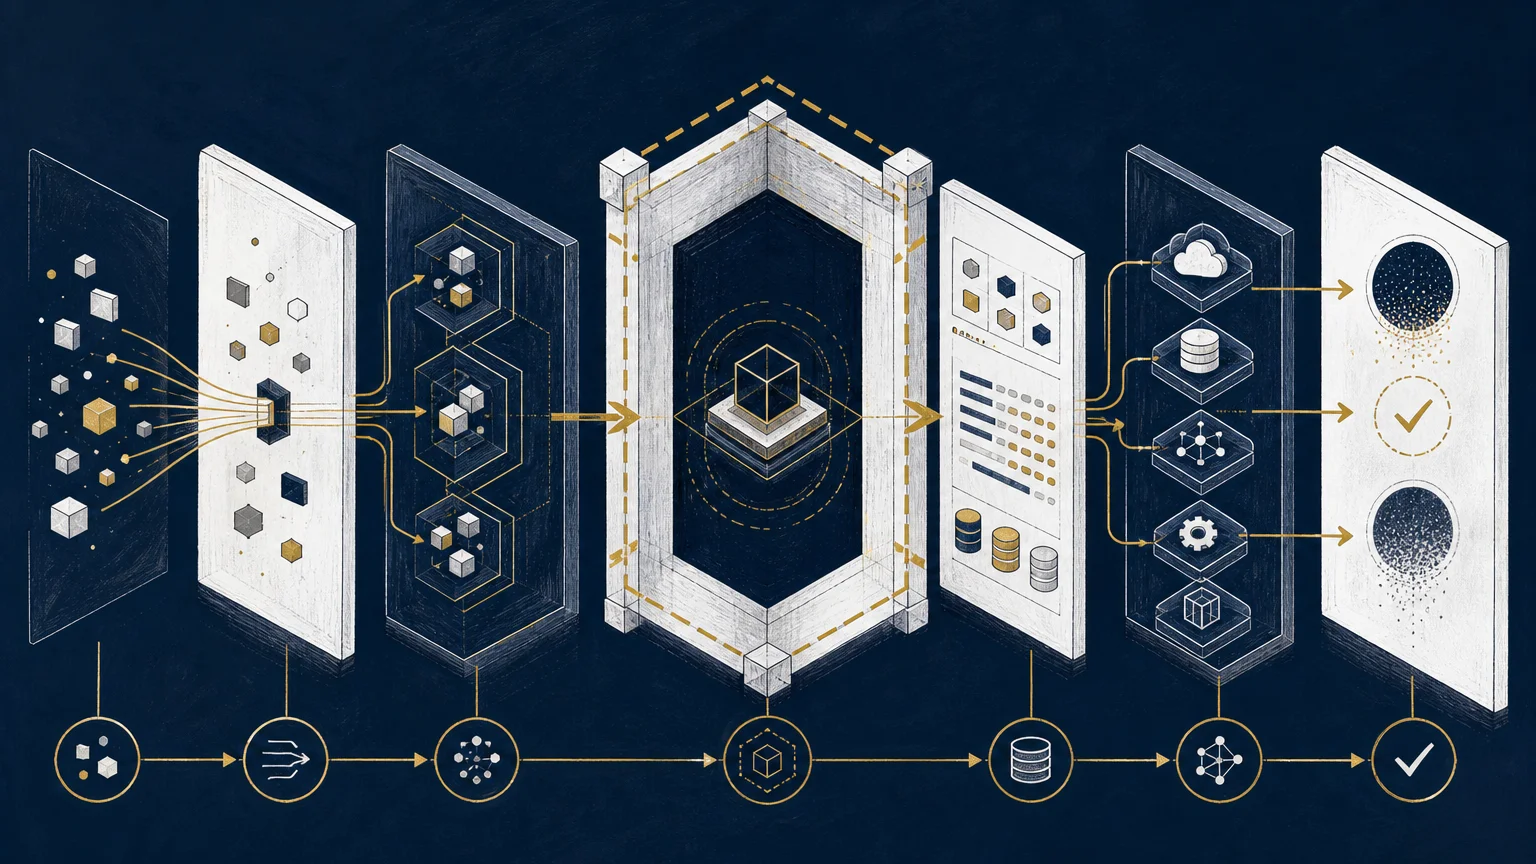
Do not begin with the provider’s headline statement. Begin with a data flow map that identifies every system touching the information.
- Define the boundary. Record the legal entity, product, model, endpoint, region, account type, and deployment route.
- List the data classes. Include prompts, files, outputs, metadata, caches, queues, agent memory, tool results, logs, backups, and derived information.
- Check the timing. Ask whether data is held in memory, written temporarily, retained for a stated period, or deleted only after a later process.
- Review exceptions. Examine abuse monitoring, safety investigations, legal holds, support access, flagged content, and feature-specific storage.
- Inspect subprocessors. Confirm whether gateways, model providers, cloud platforms, analytics services, or connected tools receive the data.
- Verify enforcement. Look for contractual language, endpoint controls, programmatic signals, audit evidence, and change notifications.
- Test failure paths. Review timeouts, retries, queues, crash dumps, support tickets, backups, and incident response procedures.
- Assign ownership. Decide which records the customer must retain for safety, audit, recovery, compliance, or appeals.
Technical evidence is more useful than a general privacy page. Ask for a retention schedule, data flow diagram, deletion procedure, subprocessor list, logging configuration, and explanation of how the control fails when an unsupported feature is selected.
The control should also fail closed where possible. If a request reaches an endpoint without the required retention setting, the gateway should block it or route it to an approved alternative. This prevents a policy from depending entirely on employee memory.
Where does Zero Data Protocol fit?
Zero Data Protocol is an emerging independent architectural framework, not a regulation, certification, product, or universal security solution. We organize it around three connected directions: Zero Collection, Zero Retention, and Zero Exploitation.
Zero Collection asks whether information is required for a clear function before it enters the system. Zero Retention asks whether information must remain after that function ends. Zero Exploitation asks whether personal traces may be reused for unrelated profiling, behavioral targeting, advertising, training, or other secondary purposes.
The framework also connects these principles to Human Freedom Choice. When identity or personal information is not functionally necessary, the system should preserve the person’s freedom not to provide it. This is relevant to anonymous access, unlinkable interactions, consent, tracking, and privacy by design.
The practical value of this broader view is sequencing. A team should not begin with the question, “How do we secure this large dataset?” It should first ask, “Does this dataset need to exist?” If the answer is yes, the next question is how long it must persist and who may use it.
Our guide to data protection by design develops this architectural perspective further. It treats privacy and security as properties that should be built into system decisions, rather than added only through notices, policies, or user instructions.
Zero Data Protocol does not claim that every system can eliminate data. Functional data, security records, accountability evidence, and connected enterprise information may remain necessary. The framework instead makes necessity the starting point and accumulation the condition that requires justification.
Build retention decisions into the architecture
Zero retention cybersecurity reduces a specific class of risk by limiting how long covered information remains available after processing. Its value depends on precise scope, reliable deletion, controlled exceptions, and visibility into connected systems. It cannot replace minimization, encryption, access control, safe agent design, or appropriate records management. The most defensible approach is to collect less, retain only what serves a defined purpose, and document what must remain. When those decisions are made at the architectural level, retention becomes an enforceable security boundary rather than a vague promise.
Take action with Zero Data Protocol
If your team is reviewing AI workflows, connected systems, or sensitive data lifecycles, zero retention should be evaluated as part of the wider architecture. The important questions are not limited to whether a provider deletes prompts. You should also examine collection, metadata, memory, downstream routing, identity dependency, and secondary use.
We provide an independent framework for examining these issues through Zero Collection, Zero Retention, Zero Exploitation, and Human Freedom Choice. Explore our zero-retention cybersecurity perspective to assess where persistent exposure is necessary, where it is avoidable, and how retention decisions connect with broader digital trust.
Frequently Asked Questions
Does zero retention mean that no data exists anywhere?
No. It usually applies to defined content, such as prompts or outputs, while account records, metadata, credentials, connected systems, security telemetry, and customer-side logs may remain.
Does zero retention prevent sensitive data from reaching a provider?
No. The data may still be transmitted and processed by the provider. Zero retention limits persistence after processing, so upstream minimization, filtering, and access controls remain important.
Is zero retention the same as a no-training commitment?
No. A no-training commitment governs model improvement, while zero retention governs storage and persistence. A provider may offer one without offering the other.
Can zero retention guarantee legal compliance?
No. Compliance depends on jurisdiction, purpose, contracts, data categories, user rights, security controls, and recordkeeping obligations. Zero retention can support a broader program, but it is not a guarantee.
How does Zero Data Protocol relate to zero retention?
Zero Data Protocol treats Zero Retention as one part of a broader framework that also addresses Zero Collection and Zero Exploitation. It additionally considers whether identity or personal information is functionally necessary, which connects to Human Freedom Choice.